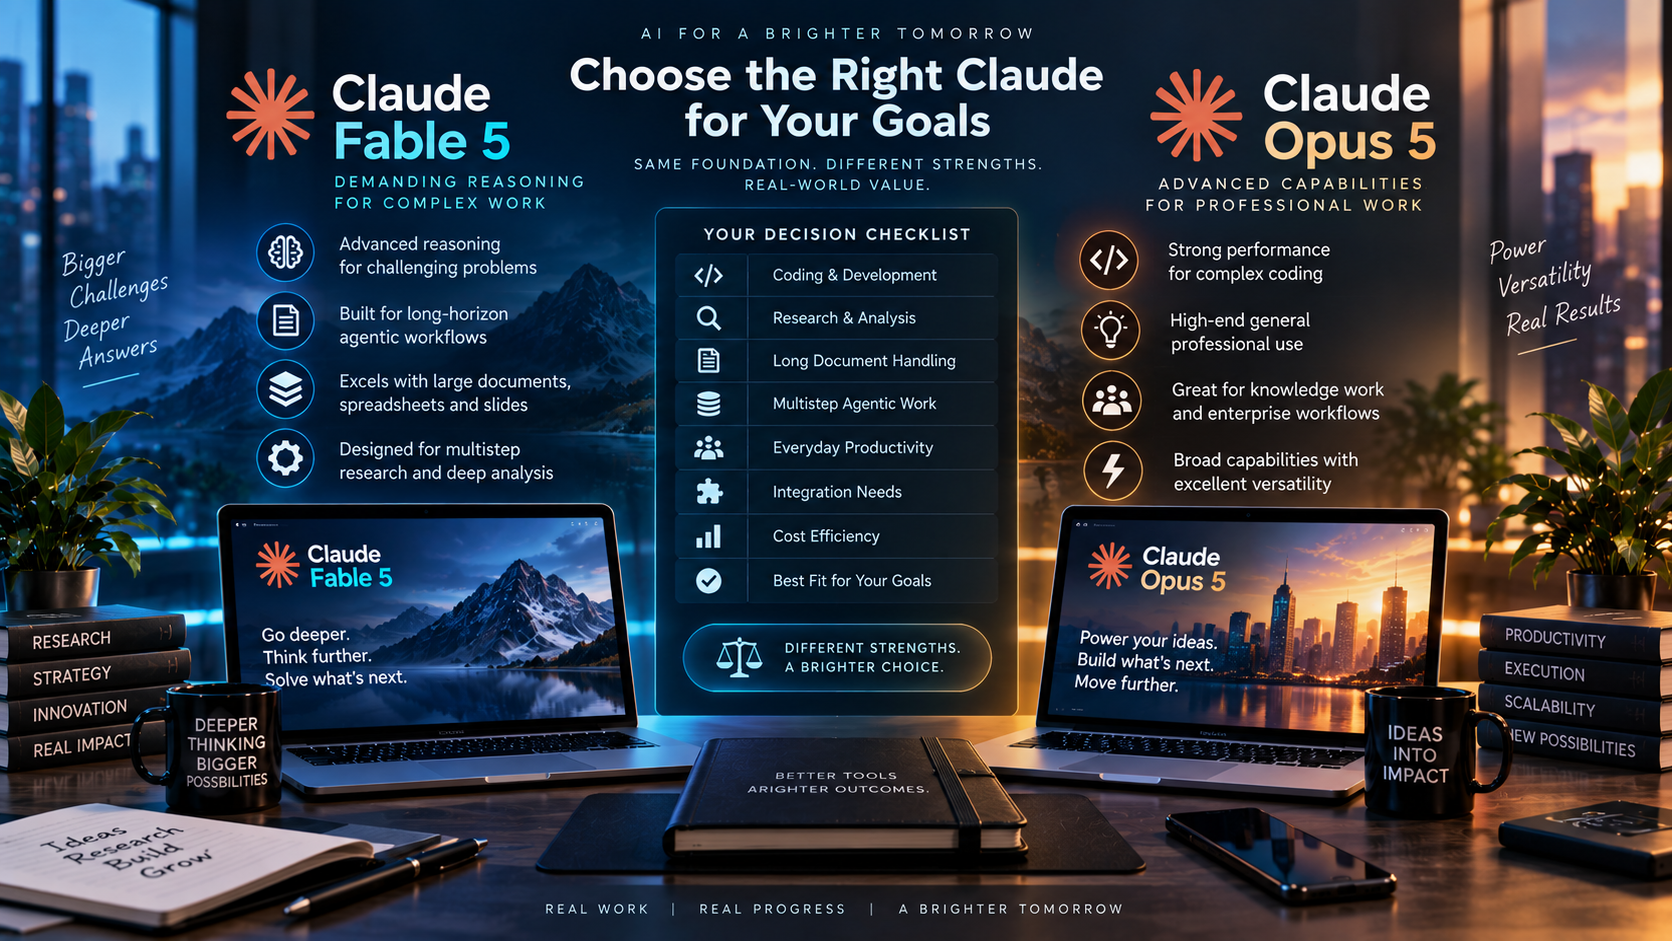
For most users, no—Claude Fable 5.1 is not automatically worth paying more for than Opus 5. Anthropic itself recommends starting with Opus 5 for most workloads and moving to Fable 5.1 when demanding reasoning or long-horizon agentic work still falls short. Fable 5.1 costs twice as much per input and output token, so its higher price makes sense primarily when its additional capabilities solve a problem Opus 5 cannot handle efficiently. If you want to explore a business-focused application of advanced Claude capabilities, check out Fable Fox AI.
The important point is that Fable 5.1 and Opus 5 are not separated simply by “good” versus “better.” They target different levels of workload complexity. Both have a 1-million-token context window and 128K maximum output, but Fable 5.1 is specifically positioned for demanding reasoning, long-running agents and multistep research.
Claude Fable 5.1 vs Opus 5: What Are You Paying For?
| Feature | Claude Opus 5 | Claude Fable 5.1 |
|---|---|---|
| Primary positioning | Complex agentic coding and enterprise work | Demanding reasoning and long-horizon agentic work |
| Context window | 1M tokens | 1M tokens |
| Maximum output | 128K tokens | 128K tokens |
| Input price | $5 / million tokens | $10 / million tokens |
| Output price | $25 / million tokens | $50 / million tokens |
| Comparative latency | Moderate | Slower |
Anthropic currently lists Opus 5 at $5 per million input tokens and $25 per million output tokens. Fable 5.1 costs $10 and $50 respectively. In other words, Fable 5.1 is priced at exactly twice the base token rates of Opus 5.
Why Opus 5 Is the Default Choice
Anthropic’s own model-selection guidance says to implement with Opus 5, optimize prompts, evaluate performance and only move to Fable 5.1 when higher-effort Opus 5 still falls short on demanding reasoning or long-horizon agentic tasks.
That makes Opus 5 particularly compelling for developers and businesses that need strong performance without automatically paying frontier-model pricing for every request.
Opus 5 is positioned for complex agentic coding and enterprise work. It also has the same 1M-token context window and 128K maximum output as Fable 5.1, so upgrading does not give you a larger basic context window.
What Does Fable 5.1 Do Differently?
Fable 5.1 is designed for situations where the AI has to sustain a complicated workflow rather than simply produce a high-quality answer.
Anthropic highlights stronger long-running agentic coding, multistep research and work involving documents, spreadsheets and presentations. Its adaptive thinking is always enabled, with a default effort level of high.
That distinction becomes important when an AI agent needs to reason through several stages, use tools, inspect intermediate results and continue toward a finished deliverable.
When Is Fable 5.1 Worth the Extra Cost?
Fable 5.1 becomes easier to justify when the cost of failure, supervision or repeated attempts is greater than the additional model cost.
For example, imagine an agent spending hours researching a complex subject, analyzing a large collection of documents and producing a finished report. If the more capable model can complete that workflow with fewer interventions, its higher token price may be offset by reduced human involvement.
On the other hand, if you’re generating straightforward content, summarizing documents, writing ordinary code or handling routine analysis, the additional cost may not provide enough practical benefit.
Does Fable 5.1 Have a Bigger Context Window?
No. This is an important misconception.
Both Fable 5.1 and Opus 5 currently have a 1-million-token context window and support up to 128K output tokens. Therefore, the reason to choose Fable 5.1 is not simply “I need more context.” Both models already provide the same headline context capacity.
The differentiator is the type and difficulty of work you want the model to perform with that context.
Fable 5.1 vs Opus 5 for Coding and Research
For coding, Opus 5 is already positioned by Anthropic for complex agentic coding and enterprise work. Fable 5.1 moves further toward long-running agentic coding and demanding research workflows.
For research, the difference is similarly about workflow depth. Fable 5.1 is specifically designed for multistep research and tasks that can continue over an extended period.
If you’re building an application, the practical approach is to benchmark both models using your actual prompts and data rather than assuming the more expensive model will always deliver proportionally better results.
Where Does Fable Fox AI Fit?
Fable Fox AI is a separate business-focused product rather than another Claude model. Its supplied product information describes a workflow centered on using advanced Claude capabilities to create business assets, with freelancers, agencies, solopreneurs and content creators among its intended audiences.
That makes it relevant if your interest in Fable 5.1 goes beyond personal productivity and toward packaging AI capabilities into potential business services.
For a broader look at Claude Fable, Opus and other leading AI models, read the complete Claude Fable 5 vs Opus 5 vs Kimi K3 comparison.
Watch the discussion: Explore the latest Claude models and the broader AI business opportunities emerging around increasingly capable AI systems.
Who Should Pay for Fable 5.1?
- Choose Opus 5 if you want strong performance for complex coding, enterprise workflows and demanding general-purpose tasks at the lower published price.
- Choose Fable 5.1 if you need long-horizon agents, multistep research or sustained complex reasoning.
- Test before upgrading by evaluating both models against your real prompts, data and edge cases.
Frequently Asked Questions
Is Claude Fable 5.1 worth paying more for?
It can be, but primarily when its additional capabilities address demanding reasoning or long-horizon agentic workloads that Opus 5 cannot handle adequately. Anthropic recommends starting with Opus 5 for most workloads. :contentReference[oaicite:7]{index=7}
How much more expensive is Fable 5.1 than Opus 5?
Fable 5.1 costs twice as much at the published base API rates: $10 versus $5 per million input tokens and $50 versus $25 per million output tokens.
Does Fable 5.1 have a larger context window than Opus 5?
No. Both currently provide a 1-million-token context window and 128K maximum output.
Which is better for long-running AI agents?
Fable 5.1 is the more specialized choice. Anthropic explicitly positions it for demanding reasoning and long-horizon agentic work, while Opus 5 is positioned for complex agentic coding and enterprise work.
Final Answer: Is Fable 5.1 Worth It?
For most users, Opus 5 is the better value. Fable 5.1 is worth paying for when you specifically need its higher-end reasoning and long-horizon agentic capabilities. Paying twice the token price makes little sense for routine workloads that Opus 5 already handles effectively. But for complex research, sustained agents, demanding coding and workflows where human supervision is expensive, the additional capability can justify the premium.
The best way to decide is to test your actual workload rather than choosing based solely on specifications. Start with Opus 5, measure the results, and move to Fable 5.1 when your evaluation shows that the additional capability produces enough value to justify the higher cost.
For the broader comparison of Claude Fable 5, Opus 5 and Kimi K3, continue with the complete AI model comparison.